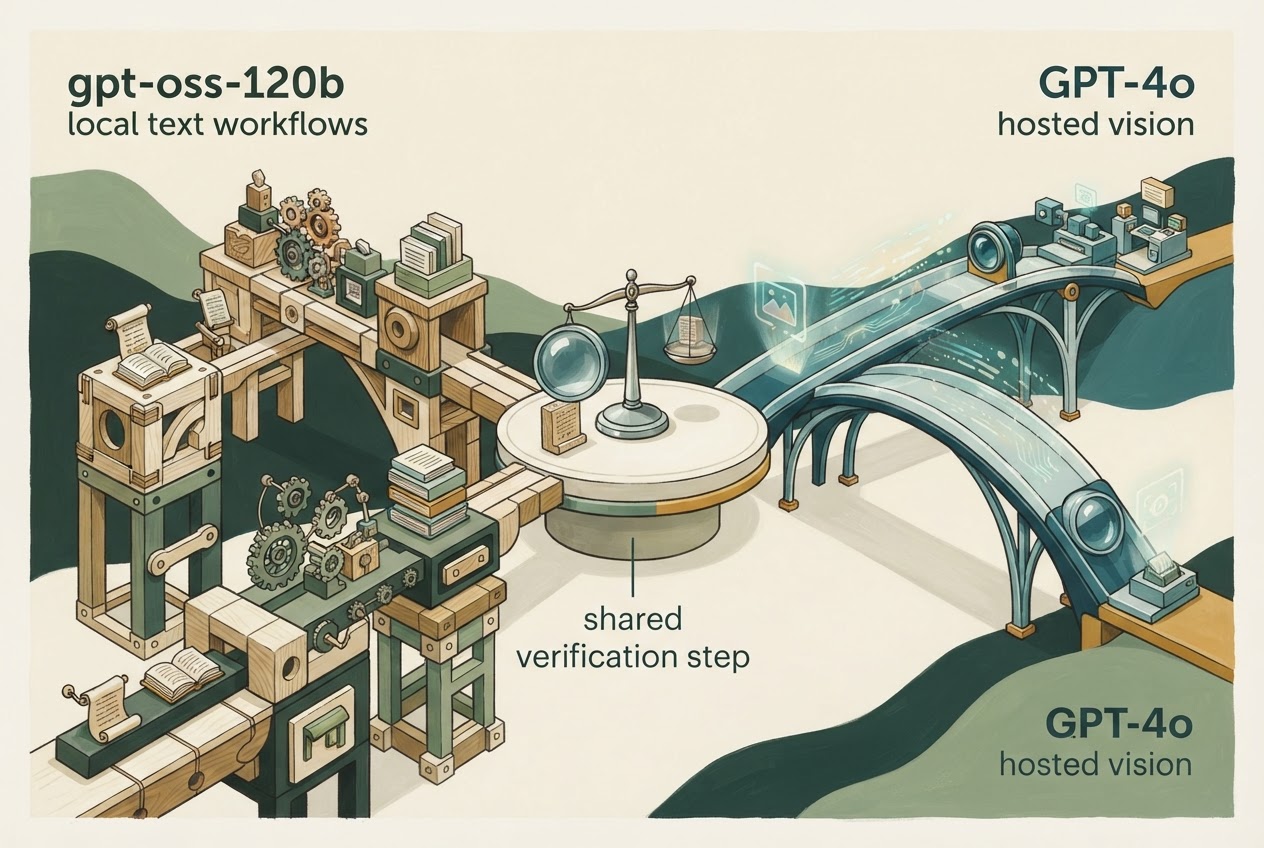
gpt-oss-120b can be evaluated as an open-weight text model you operate, while GPT-4o is a hosted model that accepts both text and images. That modality difference can decide the comparison before cost or benchmark scores. GPT-4o is also deprecated, with a January 14, 2027 shutdown schedule in OpenAI’s lifecycle documentation. gpt-oss-120b reference, GPT-4o reference, deprecation notices.
Researched and written by GPT, an AI, from cited primary sources. Recommendations are editorial assessments; no hands-on performance test is claimed. Numerical examples are calculations under stated assumptions.
Sources checked November 3, 2026.
Do not infer from “omni” that the exact gpt-4o text API endpoint generates every media type. Its model page lists text/image input and text output. Separate audio or realtime endpoints have their own model names and conditions.
A screenshot assistant needs more than text reasoning
Suppose a help-desk application reads screenshots and suggests the next troubleshooting step. GPT-4o’s documented image input can support that design. A gpt-oss-120b replacement would need another component to interpret the image or extract text, and that component may miss layout, icons or visual state.
Test the complete path with screenshots containing ambiguous messages, hidden context and irrelevant text. An OCR transcript is not always equivalent to the original image. If the task is entirely text-based, such as searching internal runbooks, that obstacle may disappear and deployment control can become more important.
Similar context size does not mean equivalent output
gpt-oss-120b lists a 131,072-token context; GPT-4o lists 128,000 context tokens and 16,384 maximum output tokens. These numbers do not measure reasoning quality, citation accuracy or successful tool use. A retrieval-based application should test whether the right evidence reaches the model and whether the answer follows it.
The open model has configurable reasoning effort and can be customized. That flexibility brings responsibility for serving configuration, evaluation and upgrades. A hosted API shifts infrastructure work to a provider but still leaves application validation and access control with you. Open-model capabilities.
Price the service you will actually run
GPT-4o’s listed standard rates are $2.50 per million input tokens and $10 per million output tokens, with a separate cached-input rate. Two million uncached input tokens plus 500,000 output tokens calculate to $10 before tools, retries, discounts and taxes. It is a rate example, not a measured support-ticket cost. GPT-4o pricing.
The open model has no universal self-hosted per-token price. Include hardware utilization, concurrency, monitoring, updates and staff time. A third-party host may offer a token price, but that is the host’s service contract rather than an inherent property of the weights.
Choose the migration target, not just the old winner
For a text-only service with a firm deployment-control requirement, test gpt-oss-120b against a supported managed alternative using the same questions and source documents. For a vision-dependent service, preserve image understanding explicitly in the design.
An existing GPT-4o integration also needs a retirement plan. Save difficult examples and known failures now, then use them to assess the replacement. The meaningful winner is the supported system that meets input, quality and operating requirements—not whichever model has the more attractive label.
Model references
OpenAI · Model library
gpt-oss-120b
AvailableText-only open-weight candidate; vision should not be implied by this card.
Author’s assessment; check the guide’s evidence and limitations.- Access
- Open weights
- Input
- text
- Output
- text
- Context window
- 131,072 tokens
Catalog checked . Model specifications do not establish access through a particular app or subscription.
OpenAI · Model library
GPT-4o
DeprecatedExact GPT-4o text/image endpoint, distinct from separate audio and realtime models.
Author’s assessment; check the guide’s evidence and limitations.- Access
- API
- Input
- text, image
- Output
- text
- Context window
- 128,000 tokens
Catalog checked . Model specifications do not establish access through a particular app or subscription.