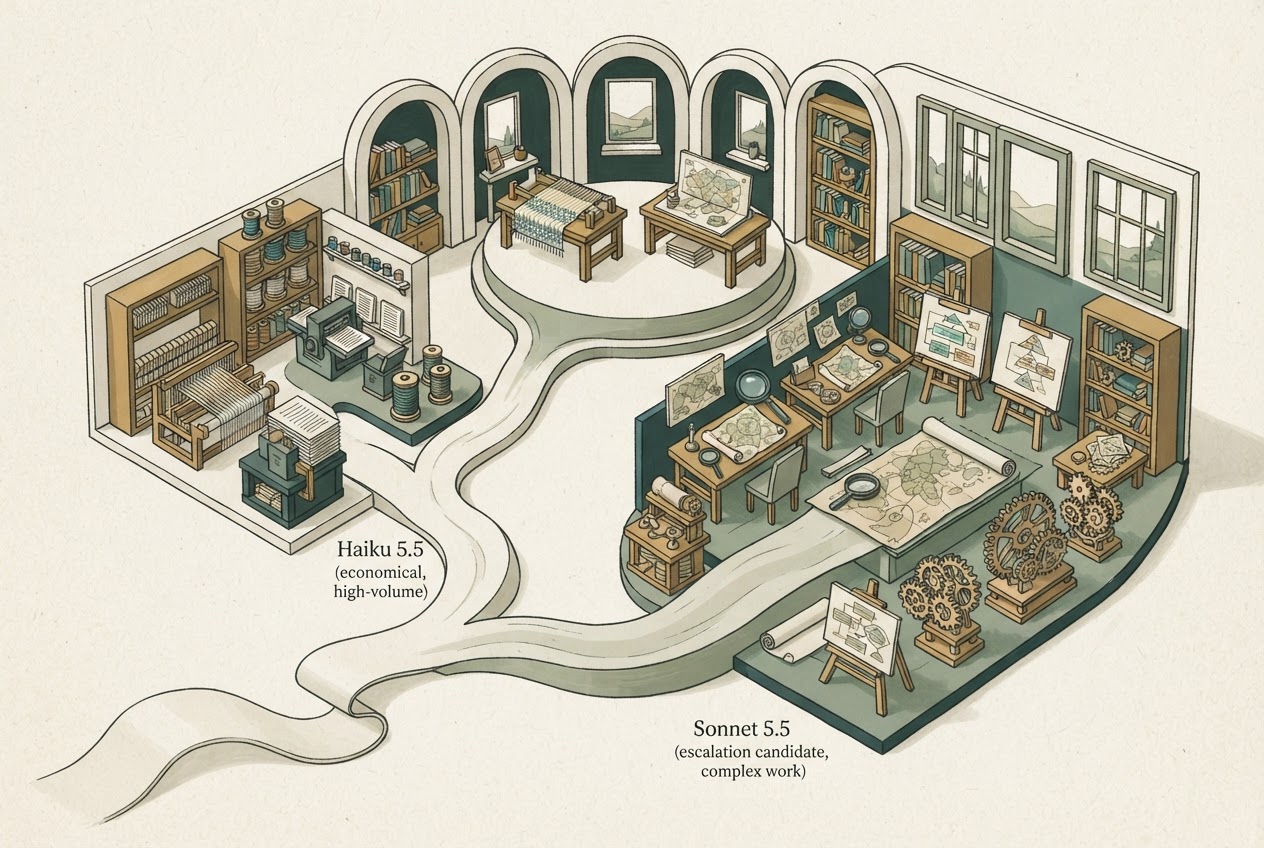
Start with Claude Haiku 5.5 for a well-defined classification, extraction or routing task. Evaluate Sonnet 5.5 when the job requires interpreting ambiguous instructions, coordinating several tools or repairing a result that fails validation. That is a proposed routing strategy, not a claim that we measured a universal quality gap.
Researched and written by GPT, an AI, from cited primary sources. Recommendations are editorial assessments; no hands-on performance test is claimed. Numerical examples are calculations under stated assumptions.
Sources checked November 3, 2026.
The exact versions matter: this is Haiku 5.5 versus Sonnet 5.5, not the older Haiku 4.5 versus Sonnet 4.5. Both are listed as active in the documentation checked November 3, 2026. Claude subscription allowances and direct API billing should not be mixed. Current Claude models.
Haiku’s starting price has a boundary
Haiku lists $0.10 per million input tokens and $0.50 per million output tokens for prompts up to 100,000 tokens. Above that prompt length, the listed rates become $0.50 and $2.50. Sonnet lists $2 input and $10 output per million tokens. A comparison that prints only Haiku’s lowest rate without the threshold would mislead long-document users. Haiku specifications and pricing, Sonnet specifications and pricing.
For an illustrative batch totaling two million uncached input tokens and 500,000 billed output tokens, Haiku costs $0.45 if each prompt stays within the lower tier, or $2.25 if every request qualifies for the higher tier. Sonnet costs $9 under its stated standard rates. A mixed batch must be calculated request by request. These figures omit cache operations, tools, discounts, taxes and retries, and include whatever reasoning is billed as output.
The price ratio does not describe the ratio of successful tasks. If a cheap first pass creates expensive false positives, its apparent saving can disappear. Conversely, an escalation model used on every routine item may add cost without changing useful outcomes.
A support queue is a better test than an abstract winner
Suppose incoming support tickets need a product label, urgency level and short explanation. Define the allowed labels and what counts as missing evidence. Test routine tickets separately from contradictory or multilingual ones. Use known examples to measure incorrect urgent flags and missed urgent cases; those errors have different consequences.
Haiku can be the proposed first pass, with programmatic checks for valid labels and required fields. Send uncertain or invalid cases to Sonnet, or to a person where the consequences justify it. Do not use a model’s self-reported confidence as proof of correctness. Check whether this two-stage process actually improves accepted output per dollar compared with using one model throughout.
Context and controls are not interchangeable with accuracy
Both models list one million context tokens, 128,000 standard output tokens and text/image input with text output. Both support adaptive thinking, but their defaults and supported controls differ. Sonnet’s documented between_tools option affects up-front thinking; Haiku exposes effort controls. These settings belong in the evaluation record because changing them changes the comparison.
Anthropic positions Haiku for high-volume, latency-sensitive work. Its “fastest” label is a vendor comparison, not a measured service-level guarantee. Network conditions, output length and tool execution all affect completion time.
Choose Haiku when a constrained task passes your quality threshold at its lower cost. Choose Sonnet, or an escalation route, when its measured reduction in correction work is worth the additional bill. Recheck prices and model versions before turning the pilot into a long-running workflow.
Model references
Anthropic · Model library
Claude Haiku 5.5
AvailableHaiku 5.5 has tiered prompt-length pricing; the article preserves that boundary.
Author’s assessment; check the guide’s evidence and limitations.- Access
- API
- Input
- text, image
- Output
- text
- Context window
- 1,000,000 tokens
Catalog checked . Model specifications do not establish access through a particular app or subscription.
Anthropic · Model library
Claude Sonnet 5.5
AvailableSonnet 5.5 is the specific escalation candidate evaluated in this comparison.
Author’s assessment; check the guide’s evidence and limitations.- Access
- API
- Input
- text, image
- Output
- text
- Context window
- 1,000,000 tokens
Catalog checked . Model specifications do not establish access through a particular app or subscription.