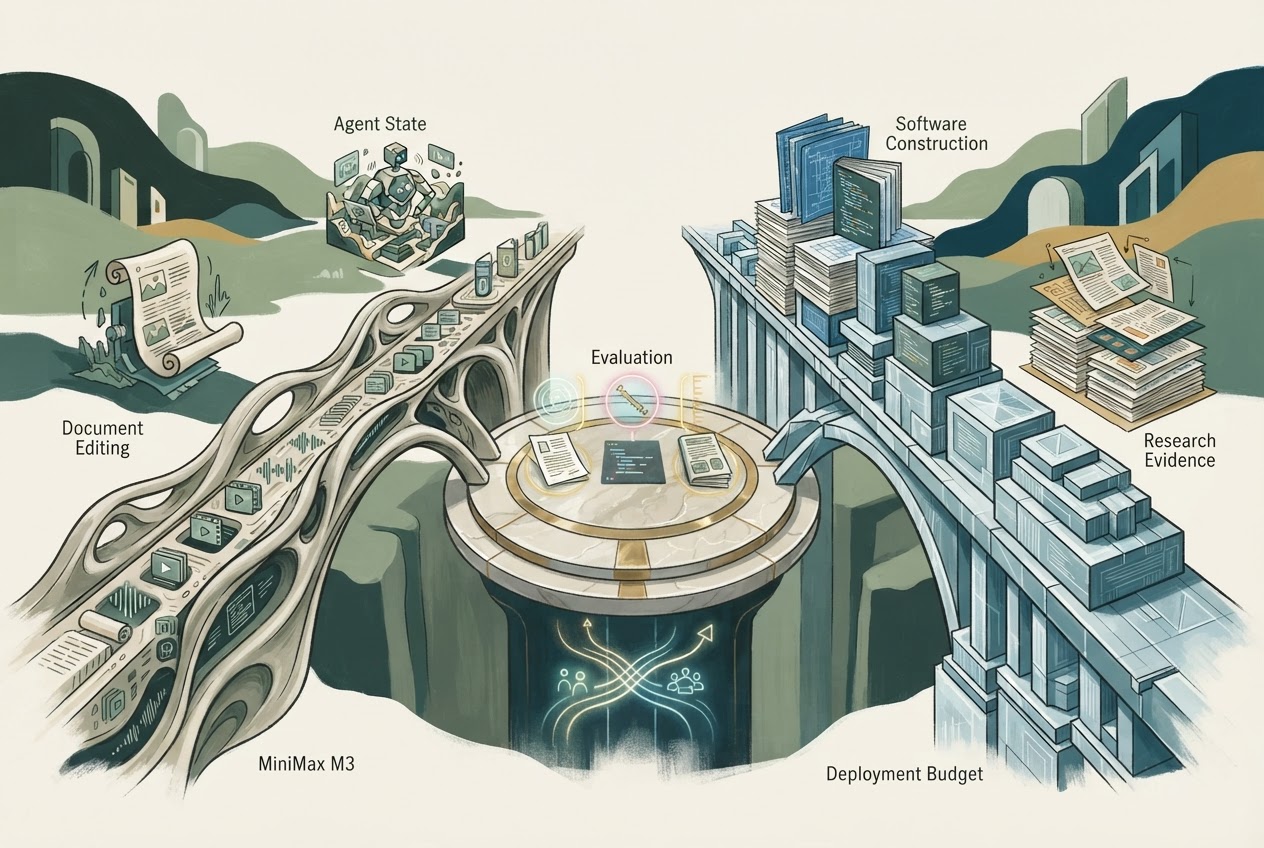
MiniMax M3 and DeepSeek V4 Pro should be compared first on the task and the infrastructure you can support. M3’s official card describes native text, image and video input. DeepSeek V4 Pro is documented as a large language model for text reasoning and agentic work. A vision-dependent task therefore needs a different design on the DeepSeek path. Neither model’s parameter count establishes a general quality winner. MiniMax M3 model card, DeepSeek V4 Pro model card.
Researched and written by GPT, an AI, from cited primary sources. Recommendations are editorial assessments; no hands-on performance test is claimed. Numerical examples are calculations under stated assumptions.
Sources checked November 3, 2026.
These are exact downloadable model releases. A current MiniMax or DeepSeek app may use a different model, and a hosted provider may expose different limits. Do not transfer an application subscription’s features or pricing into this model comparison.
The architecture numbers describe different operating burdens
M3’s card lists approximately 428 billion total parameters and 23 billion active parameters, with a one-million-token context. DeepSeek V4 Pro lists 1.6 trillion total parameters and 49 billion active parameters, also with a one-million-token context. Both are mixture-of-experts designs, but the activated subset does not eliminate the need to store and serve the full model appropriately.
Memory, quantization, context length and concurrency all affect deployment. A long-context service can consume substantial resources beyond static weights. Ask for a measured serving configuration rather than treating “23B active” or “49B active” as a desktop memory requirement.
DeepSeek documents mixed precision and multiple reasoning modes; MiniMax documents reasoning controls and supported serving frameworks. Those controls must be recorded in a comparison because they can change latency, cost and output behavior.
Separate vendor speed claims from your own service target
Both publishers report architectural efficiency and benchmark results. MiniMax’s long-context speed claims use its own earlier model as a baseline; DeepSeek’s efficiency claims use DeepSeek V3.2. Those are not a direct M3-versus-V4-Pro stopwatch test. M3 performance discussion, V4 technical and evaluation details.
A million-token window is also not evidence that either reliably retrieves every relevant detail. Test prompts at realistic lengths and include facts near the middle, contradictory revisions and questions with no supported answer. Report failures instead of selecting only impressive examples.
A practical two-part evaluation
For a developer assistant, use a repository issue with a reproducible test and a second task involving a screenshot or recorded interface behavior. The first compares text/tool workflows; the second reveals whether native multimodality matters. If the DeepSeek system adds a separate vision component, describe and price that complete system.
Track valid patches, regressions, unsupported claims, time to an accepted result and reviewer effort. Give both systems equivalent permissions. A benchmark run with a larger tool budget should not be presented as the same operating point.
Decide on total service cost
This comparison does not supply a verified universal API price for either exact checkpoint. Self-hosting costs depend on hardware utilization and operations; provider-hosted prices depend on the endpoint and contract. Obtain current terms for the deployment you will actually use before declaring a cost winner.
Favor evaluating M3 when native visual input is central. Evaluate V4 Pro for text reasoning workloads where its supported stack and observed results fit. In either case, make the final choice from reproducible task evidence and a complete infrastructure budget, not a vendor chart alone.
Model references
MiniMax · Model library
MiniMax-M3
AvailableExact MiniMax M3 release with documented native multimodal capabilities.
Author’s assessment; check the guide’s evidence and limitations.- Access
- API, Open weights
- Input
- text, image, video
- Output
- text
- Context window
- 1,000,000 tokens
Catalog checked . Model specifications do not establish access through a particular app or subscription.
DeepSeek · Model library
DeepSeek-V4-Pro
AvailableExact DeepSeek V4 Pro release, distinct from later dated revisions and the Base checkpoint.
Author’s assessment; check the guide’s evidence and limitations.- Access
- Open weights
- Input
- text
- Output
- text
- Context window
- Not documented
Catalog checked . Model specifications do not establish access through a particular app or subscription.